We keep working hard to make our products the best on the market — and we are shipping a new version of our OCR system. Provision OCR 0.9.3 reads handwriting, recognizes documents in a chosen language, processes PDFs page by page and straightens skewed scans. Here is what it means in practice and what changed in the API.
✍️ Russian handwriting
Application forms, statements and waybills filled in by hand are where classic OCR usually gives up. Version 0.9.3 adds a dedicated mode for handwritten Russian: words are found by masks and read by a purpose-trained handwriting model.
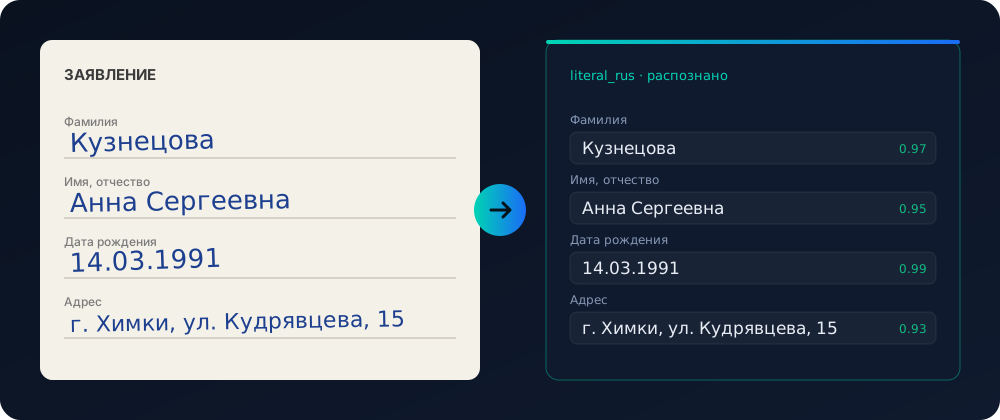
Enable it with language=literal_rus. Table extraction is disabled in this mode — it focuses on text.
🌍 Multilingual: pick the recognition language
By default the OCR decides by itself which words are Cyrillic and which are Latin. When the document language is known in advance, you can now set it explicitly for maximum accuracy:
rus— everything is read by the Russian recognizereng— Latin: output limited to digits, punctuation and ASCII letters, an out-of-set character is replaced with the most probable allowed one (café → cafe)rus,engor no parameter — both scripts with the automatic router, as beforeliteral_rus— handwritten Russian
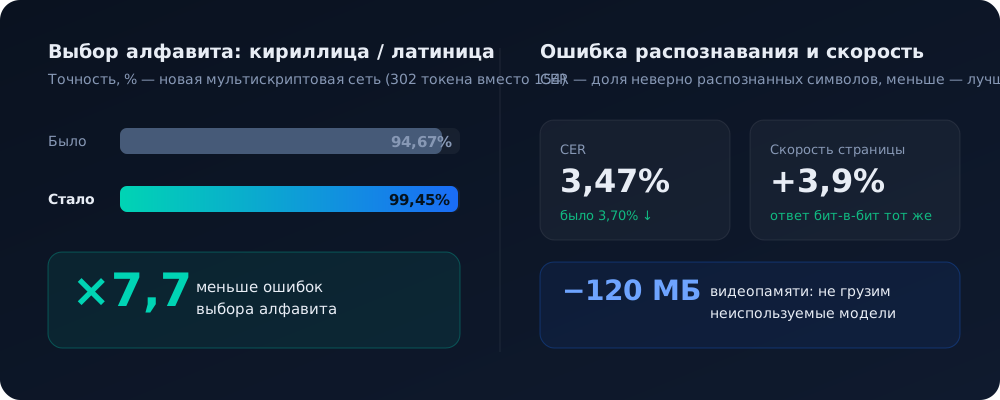
The automatic script choice itself became much more accurate thanks to a new multi-script network.
📑 Page-by-page PDF processing
Large documents and multi-page contracts can now be processed in page windows — no size limits and no extra load. Pass a range in the request, and the response reports the real page count so the client can paginate a PDF without a probe request. Page numbers in the response stay original — no renumbering.
📐 Skewed and tilted scans
A document photographed with a phone at an angle is no longer a problem. The server detects the residual page skew and straightens it before recognition. It is careful about it: a skew below 4° is left alone, and the angle is applied only when the text lines on the page confirm it.
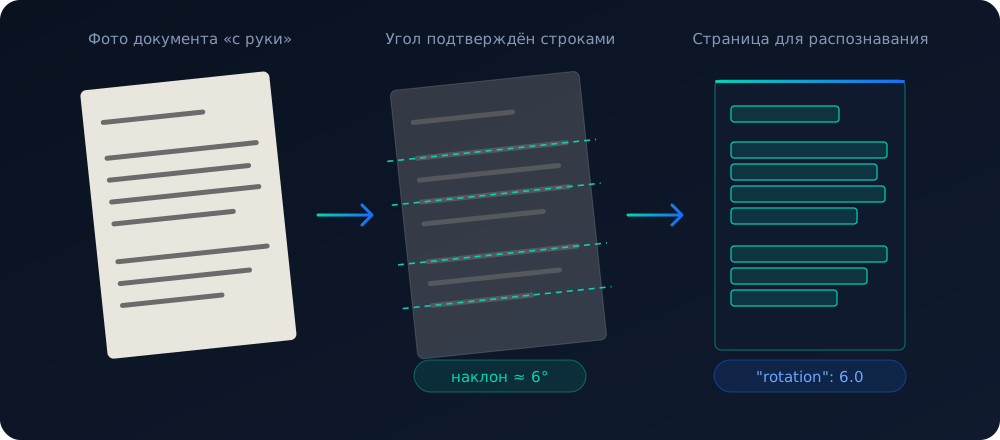
The angle the server applied is returned in the rotation field — handy for monitoring incoming scan quality.
API changes
All changes are backward compatible: no endpoint or field was removed and the new parameters are optional. Existing integrations keep working as is.
New POST /processing/{template} parameters
| Parameter | Purpose |
|---|---|
language | Recognizer choice: rus, eng, literal_rus, comma-separated. Default is rus,eng with automatic script choice. Unknown value — 400. |
pagesFrom | PDF only: first page of the range, 0-based, inclusive. Default 0. |
pagesTo | PDF only: end of the range, exclusive (pagesFrom=0&pagesTo=3 — the first three pages). Default — through the last page. |
curl -X POST "http://localhost:8098/processing/agreement?pagesFrom=0&pagesTo=10" \
     -F "file=@contract.pdf"

curl -X POST "http://localhost:8098/processing/default?language=literal_rus" \
     --data-binary @form.jpg
New response fields
documents[].pagesFrom,pagesTo,maxPages— PDF only: the requested range and the real page countpages[].rotation— clockwise angle the server turned the page by before recognition (e.g.-7.43). Absent when the page was not analysed — absence is not 0.loccoordinates stay in the delivered page frameblocks[].det_prob— detector confidence in the word box itself. Complementsprob: a highprobwith a lowdet_probmeans a confidently read but dubious region
{
  "documents": [{
    "pagesFrom": 0, "pagesTo": 10, "maxPages": 37,
    "pages": [{
      "page_number": 1,
      "rotation": -7.43,
      "blocks": [{ "text": "Contract", "prob": 0.99, "det_prob": 0.94 }]
    }]
  }]
}
Service endpoints
POST /license/activate— new: online license activation by code without a restart. Works even on a locked server, a repeated call with the same code does not consume a new slotPOST /health— now also returns the running buildversion, e.g.{"status": "ok", "version": "0.9.3"}POST /reload_service— re-readsprovision_ocr.iniand switches models without restarting the process. The config is validated as a whole before applying (an error answers 400 and leaves the running settings untouched), a second concurrent call gets 409
Under the hood: full changelog
Added
- Automatic residual page skew correction — on by default, skew below 4° is left alone, the angle is applied only when confirmed by text lines
- Page
rotationfield in the API response - “Second opinion”: a word below the confidence threshold is re-read by the other script’s recognizer and the more confident result wins
Improved
- Script choice (Cyrillic/Latin) moved to a new multi-script network — 302 tokens instead of 154: accuracy up from 94.67% to 99.45%, 7.7× fewer script errors, CER down from 3.70% to 3.47%
- Page processing is 3.9% faster with a bit-for-bit identical response: faster text detector post-processing, a heat-map cache, unused models are no longer loaded — about 120 MB less video memory
- The Windows installer ships 18 models (fp16, ~1.06 GB) and 9 class lists — exactly what the server requests on startup
Fixed
- Text no longer disappears from the response on a degenerate table grid
- Dashed rulings are now recognized as table separators — previously the table collapsed into a single row or column
- Phantom table columns eliminated
- A thick or slanted ruling no longer produces two rows instead of one at the table edge
- Half of a table is no longer mistaken for an outer frame, losing the other half
Removed
- Two models that are no longer used were removed from the installation bundle
Supported GPUs and packages
| GPU | Windows | Docker |
|---|---|---|
| NVIDIA RTX 40xx (Ada Lovelace) | 2.3 GB | 8 GB |
| NVIDIA RTX 30xx (Ampere) | 2.3 GB | 8 GB |
| NVIDIA RTX 20xx (Turing) | 2.3 GB | 8 GB |
| NVIDIA 10xx (Pascal) | 2.3 GB | 8 GB |
| AMD Radeon RX 6xxx (RDNA 2) | 2.3 GB | 8 GB |
docker pull registry.provlabs.tech/hub/provision_ocr:latestThe Windows installer and instructions are on the download page, API details are in the documentation.
And that is not all
We are also preparing a Provision LLM Engine release — a significant speed-up on modern GPUs.
👉 Provision OCR · 🧠 Provision LLM Engine · 💬 Follow the updates on Telegram: @ProvisionLabs